 GPU Cloud G96 from $1,922/mo · about $2.63/hr · VAT extra
The whole card is yours
1:1 PCI passthrough maps the full RTX PRO 6000 to your server. No vGPU slicing and no noisy neighbours.

A dedicated RTX PRO 6000 with 96 GB of VRAM, CUDA pre-installed and no per-hour meter.
RegionEurope (DE)
StackCUDA · Docker
$ ollama run llama3.3:70b
✓ 70B model loaded · FP8 · 69.8 GB VRAM
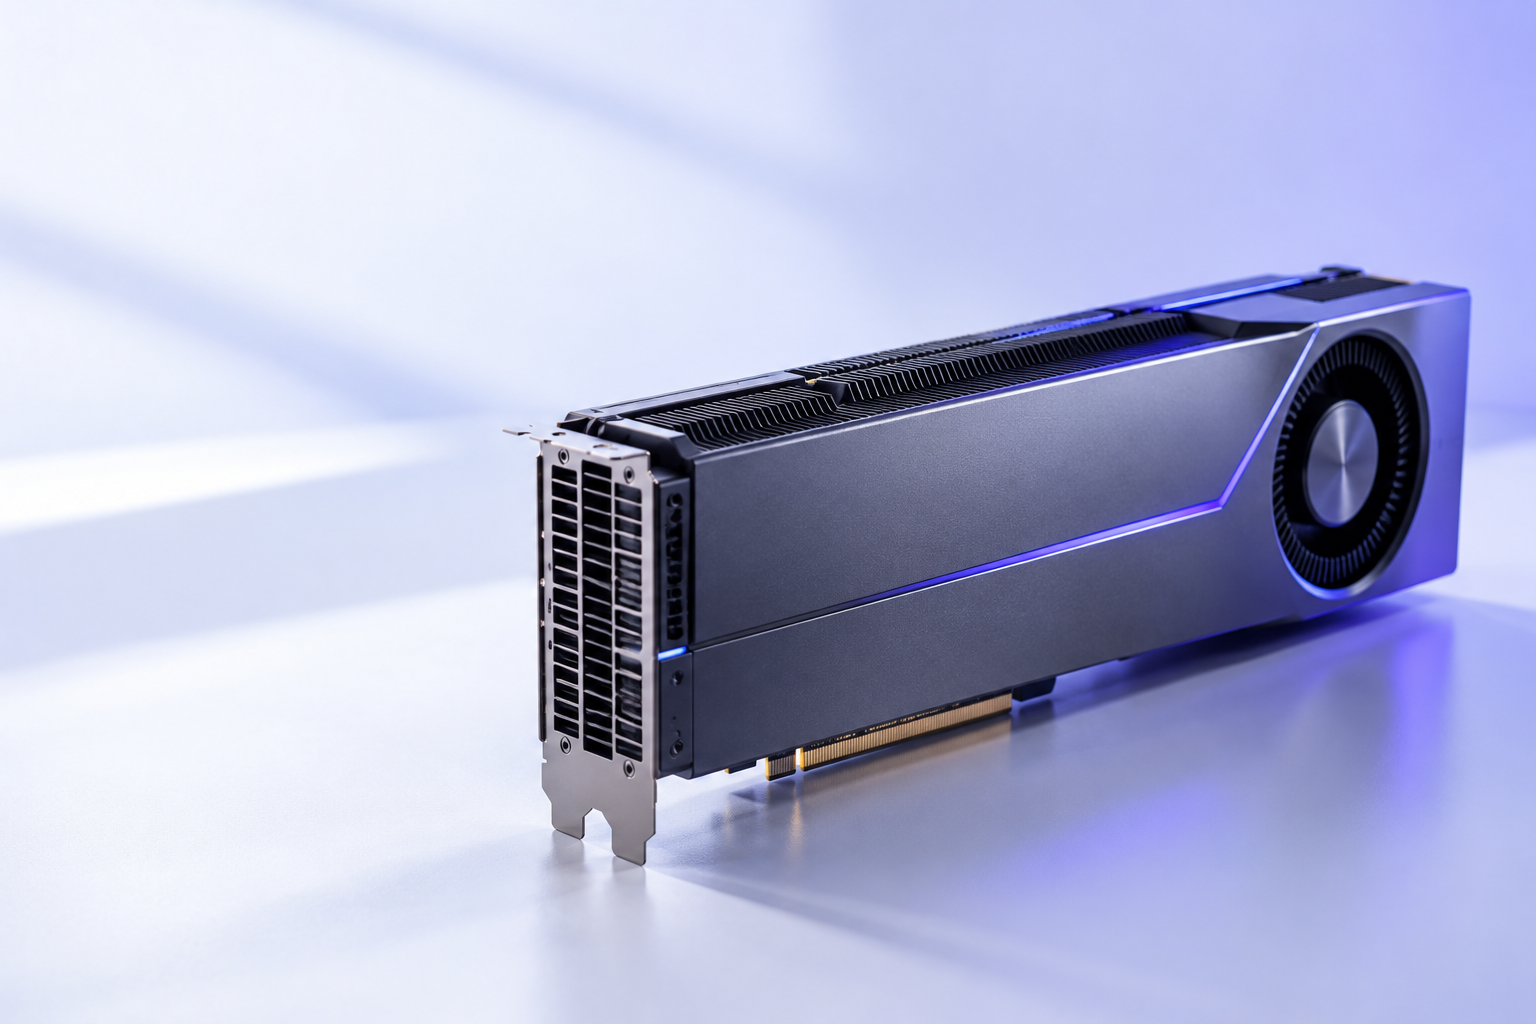
A sliced or shared GPU is fine for experiments. When the model is your product, you want the full card, the full memory and a bill you can predict.
1:1 PCI passthrough maps the full RTX PRO 6000 to your server. No vGPU slicing and no noisy neighbours.
No per-hour meter and no surprise egress bill. Traffic is unmetered under fair use.
Ubuntu 24.04 with NVIDIA drivers, the CUDA toolkit and the container toolkit already installed.
Only need CPU for an AI assistant? AI App Hosting from £8.21/mo →
Prices exclude VAT. Pay monthly, or lock in a lower rate for 12 or 24 months.
NVIDIA RTX PRO 6000 Blackwell Server Edition · 96 GB GDDR7 ECC
32 CPU cores · 234 GB RAM · 1.75 TB · 15 TB traffic · EU data centre
Best for: Inference, graphics and video
Configure32 CPU cores · 234 GB RAM · 1.75 TB · 15 TB traffic · EU data centre
Best for: Rendering, design and mid-size LLMs
Configure32 CPU cores · 234 GB RAM · 1.92 TB · 15 TB traffic · EU data centre
Best for: 70B at FP8 and fine-tuning
Configure32 CPU cores · 234 GB RAM · 1.9 TB · 15 TB traffic · EU data centre
Best for: Long context and training
Configure8× H200 HGX (1,128 GB) from £28,855/mo, or 8× B300 with 400G InfiniBand. Sized with you on a call.
Every GPU server includes root access, DDoS protection and a free firewall.
Rough VRAM for model weights alone. Leave 10–20% headroom for context and batching.
Serve Llama, Qwen or Mistral behind your own API. Customer data stays on your server.
Adapt open models to your documents and tone on a single, predictable node.
Run diffusion and video models without queueing for shared capacity.
ISV-certified for Maya, Houdini and Cinema 4D. Render overnight at a fixed cost.
Single-node CFD, molecular dynamics and FEM workloads with ECC memory.
Hardware video encoders for streaming, archives and social cut-downs.
No driver installs and no provisioning queue. The basics are done before you log in.
Europe or US Central, close to your users or your data.
Ubuntu 24.04 with NVIDIA drivers, CUDA toolkit and container toolkit.
Pull your model or container and start working straight away.
One RTX PRO 6000-class GPU running all month. On-demand cloud GPUs bill every hour, even when you forget to switch them off.
Sizing a workload? An engineer will check it with you before you buy.
Dedicated. The full card is passed through 1:1 to your server. There is no vGPU slicing and no one else’s jobs on it.
Yes, many 70B deployments fit at FP8 or lower precision. Context length, batching and runtime overhead still need sizing.
Yes. Ubuntu 24.04 arrives with the NVIDIA driver, CUDA toolkit and NVIDIA container toolkit installed.
GPU Cloud is available in Europe and US Central, subject to live stock.
Yes, through a planned migration. Our engineers will confirm downtime and data-transfer steps first.
Linux is the standard GPU image. Ask an engineer about Windows licensing and availability for dedicated configurations.
Tell us the model and the workload. We will size it with you and have CUDA running the same day.
